Relative pose estimation is fundamental to collaborative perception and coordination, yet robots often meet only briefly, communicate over limited bandwidth, and lose visual overlap through occlusion or restricted fields of view. Existing approaches commonly rely on global references, sustained overlap, or expensive visual transmission.
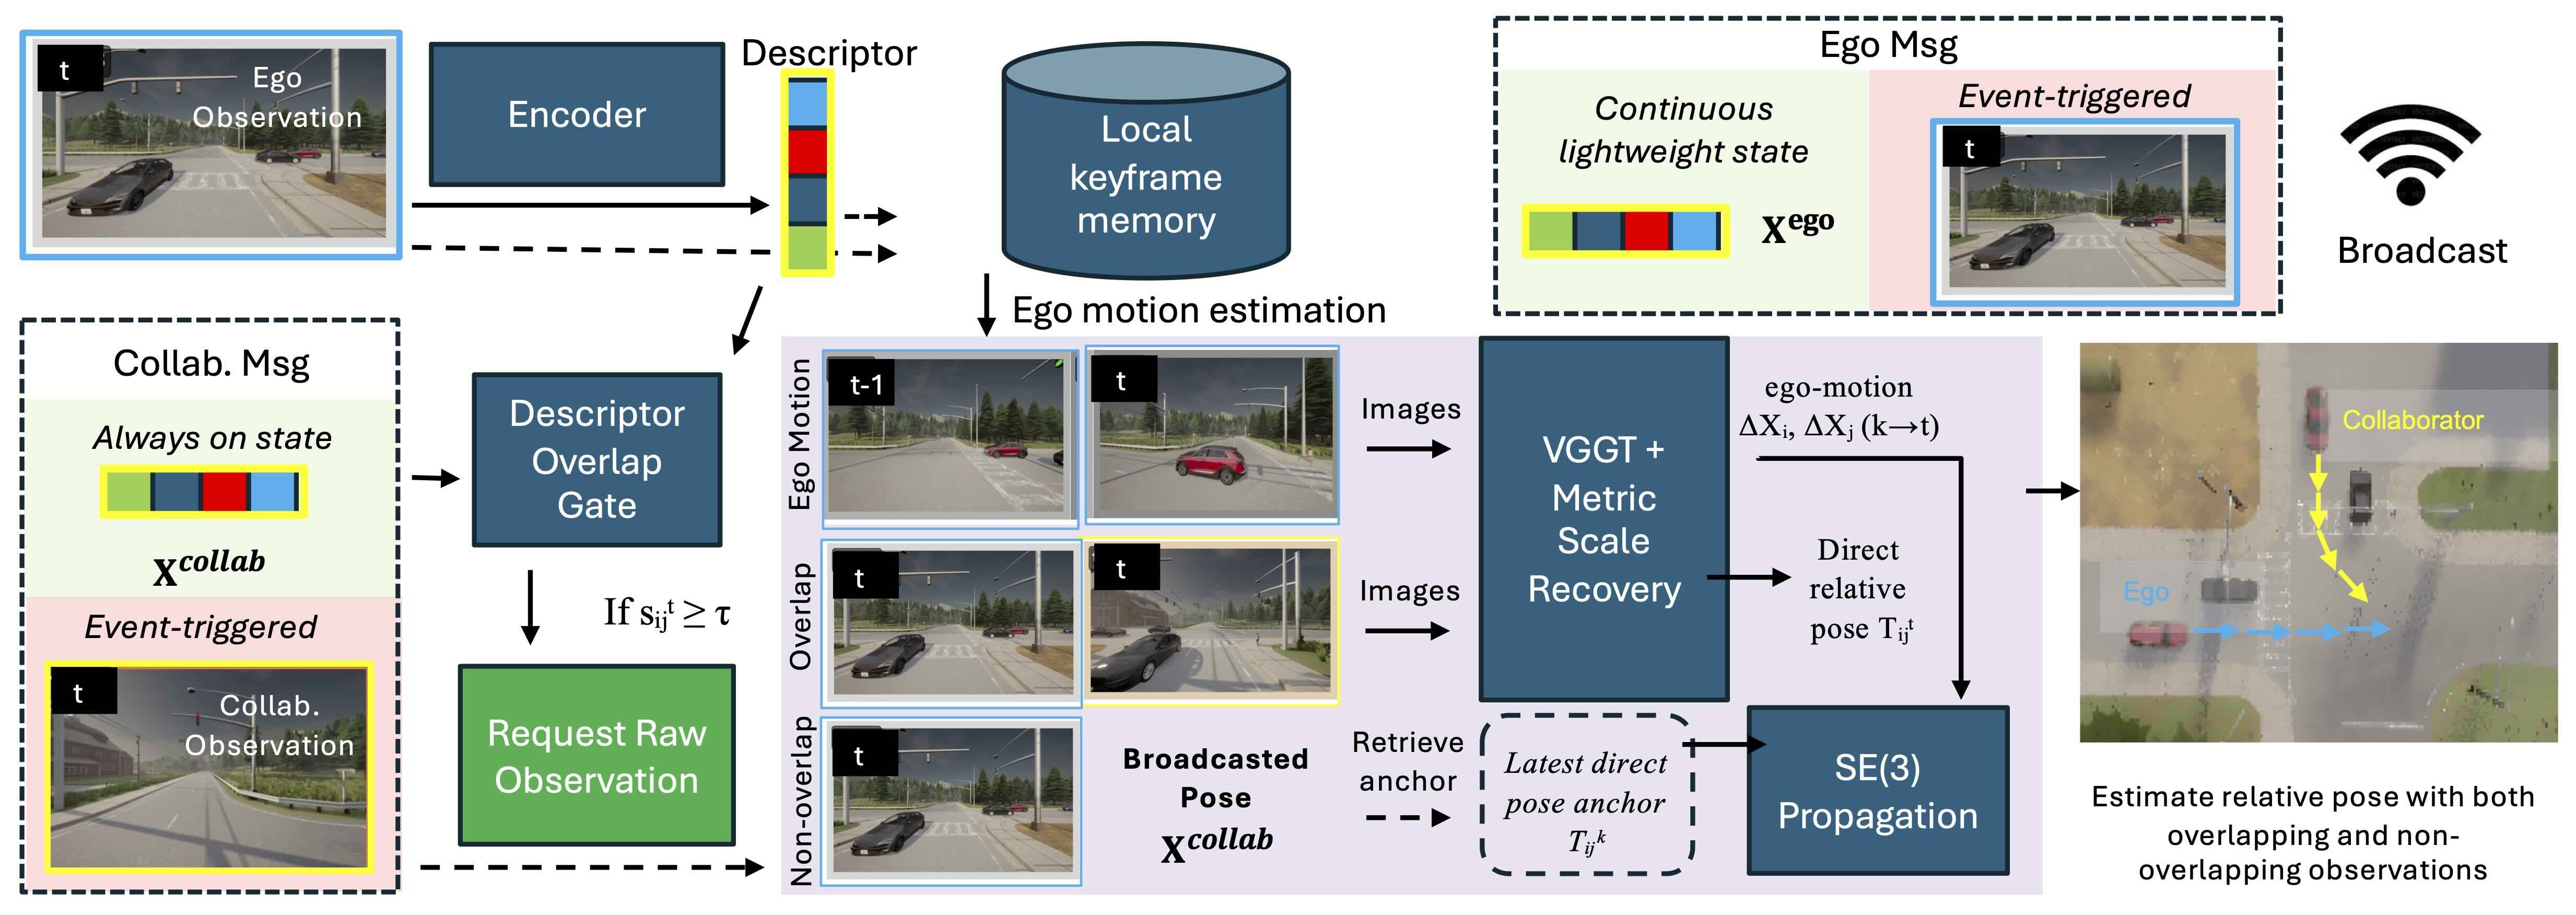
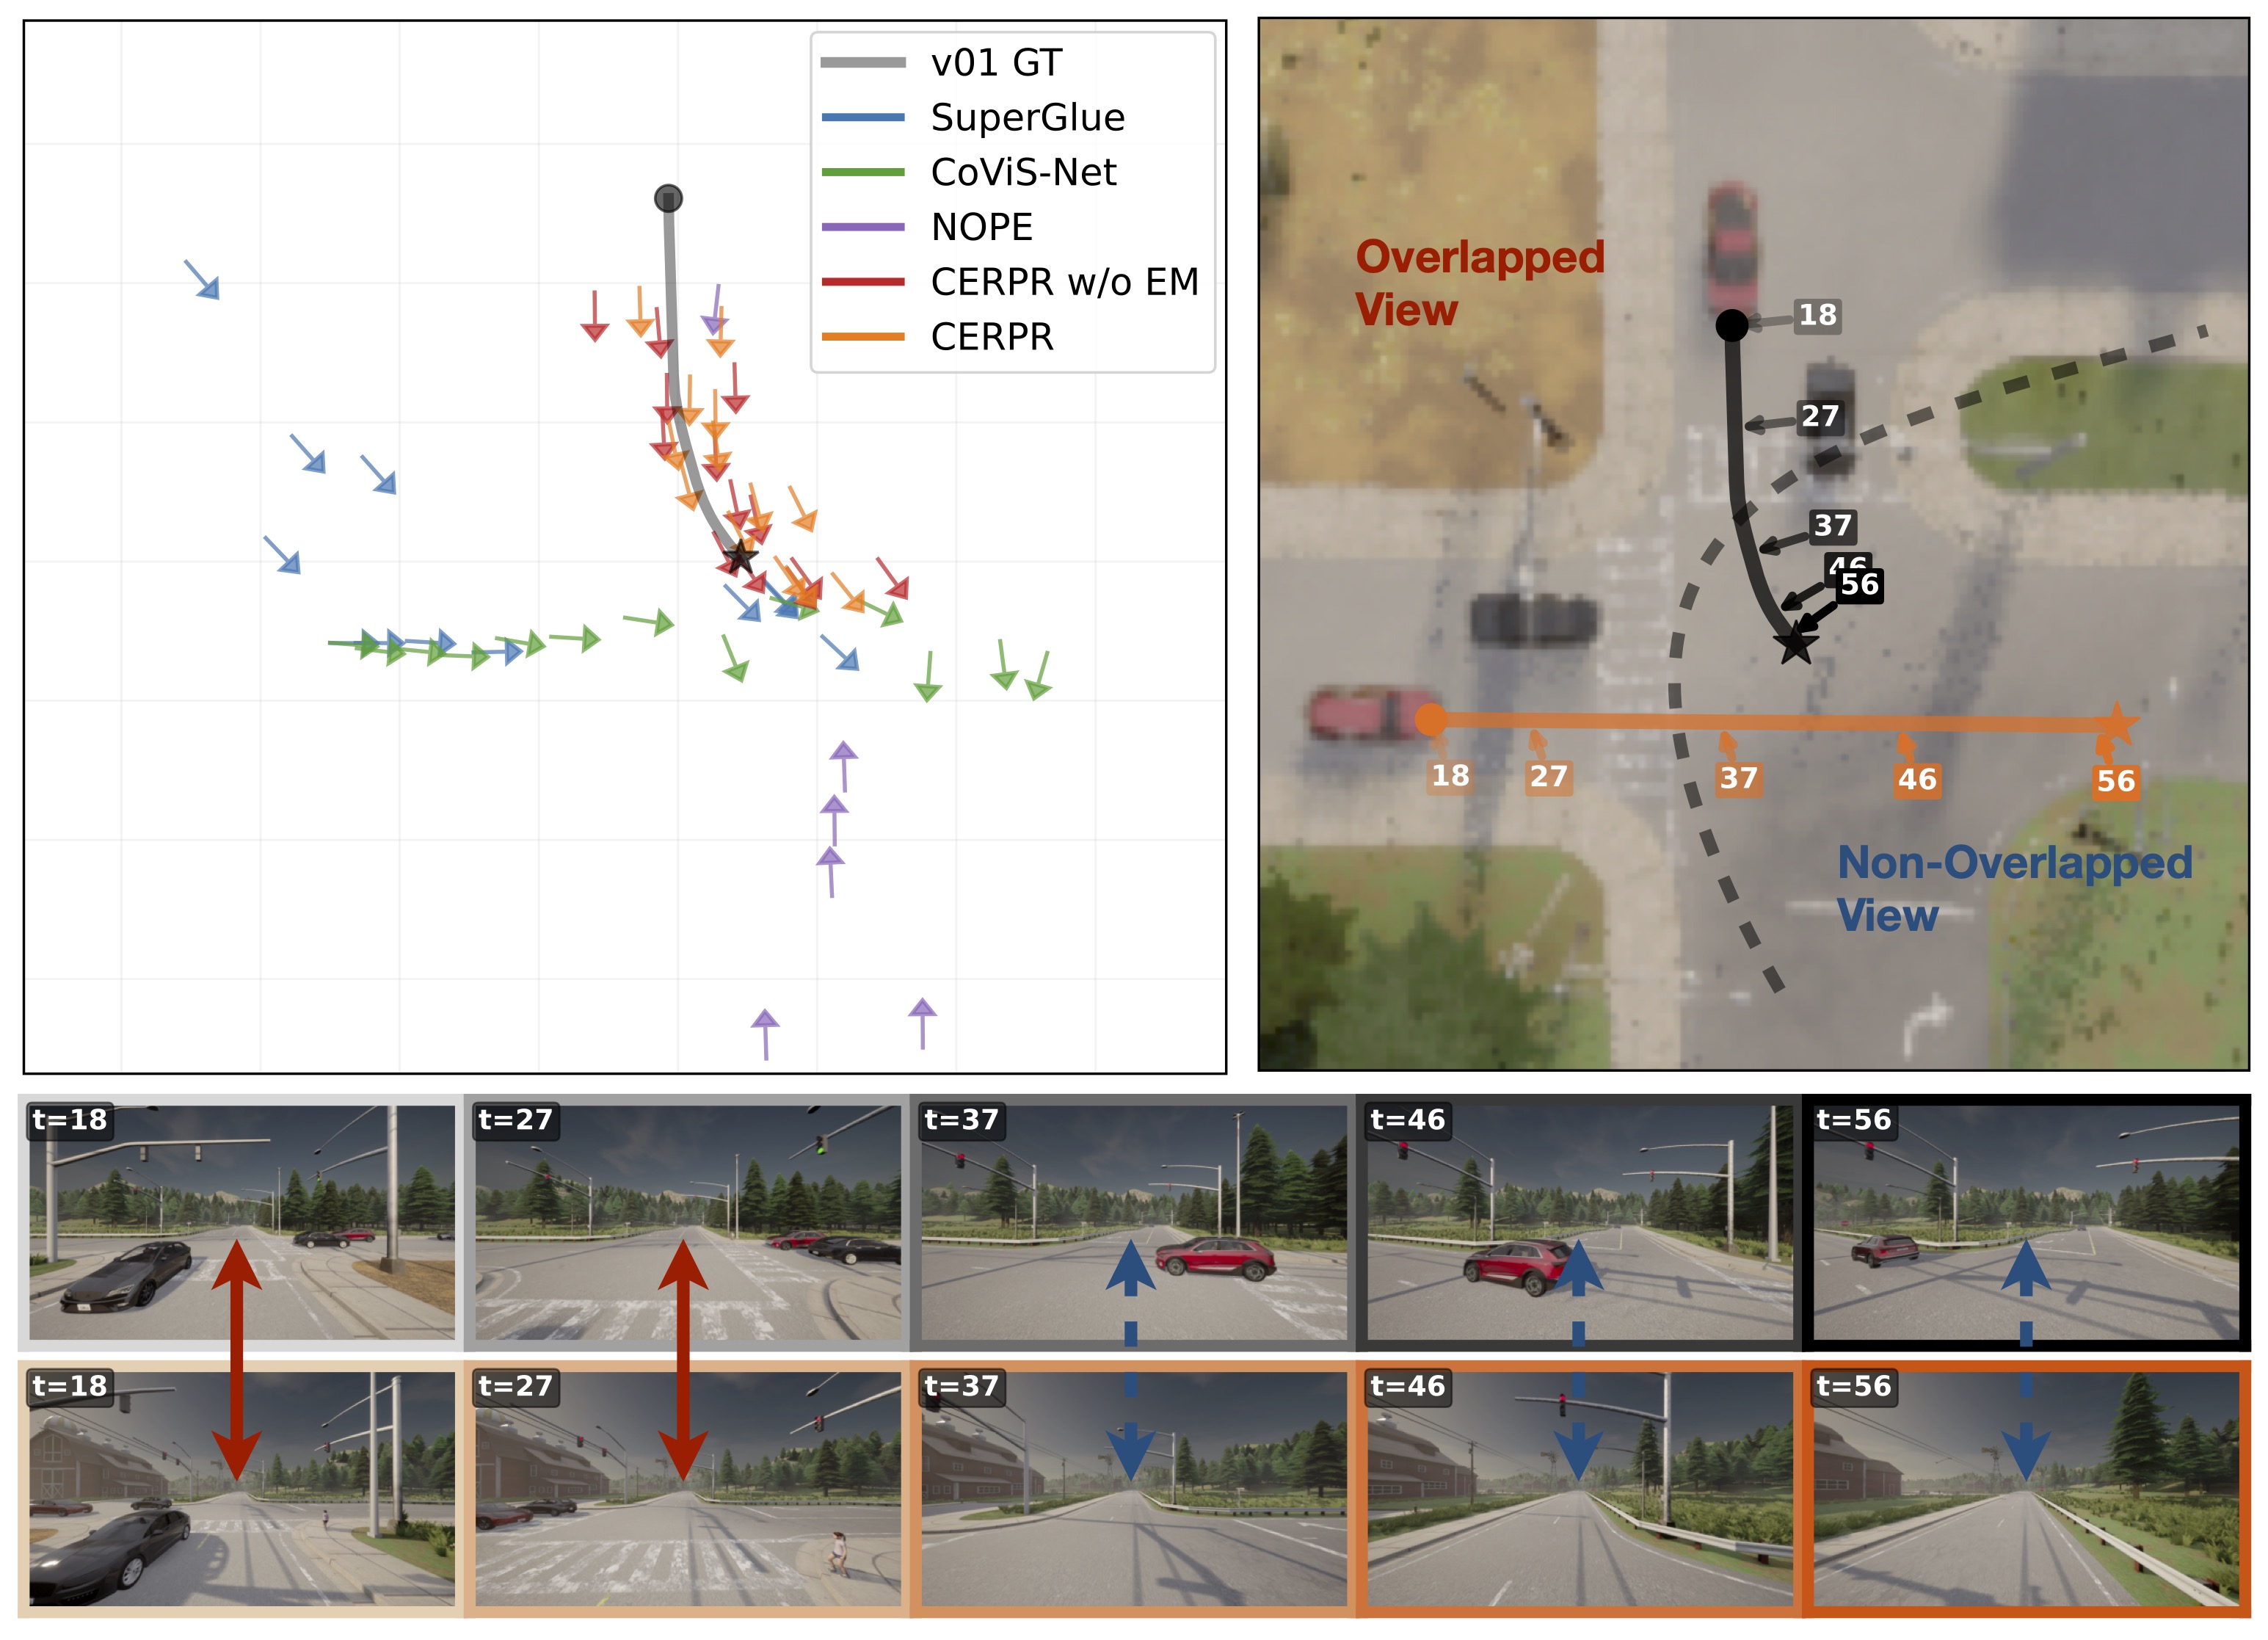
CERPE is a system-level framework that coordinates existing large-scale pre-trained vision models for metric ego-motion and inter-robot relative pose estimation. Robots continuously exchange fixed-size descriptors and local poses; descriptor similarity gates event-triggered raw-image requests. Direct estimates anchor the relative geometry when views overlap, while metrically scaled ego-motion propagates the latest anchor through non-overlapping intervals.
TL;DR: Screen overlap cheaply, request images selectively, and keep relative pose continuous when the shared view disappears.